September 2, 2025 · Jan Hoppe
Your Brain on ChatGPT – LLMs Make Bad (Product) Coaches
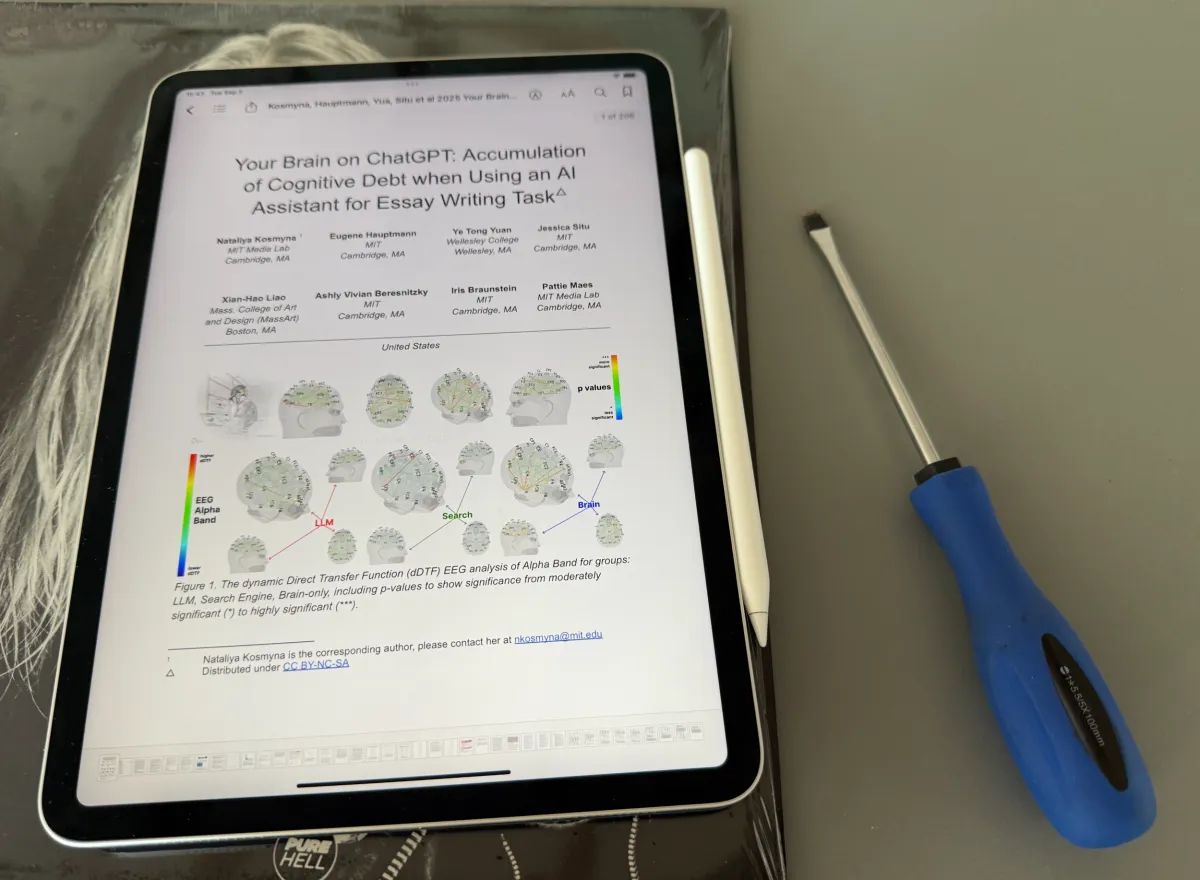
Like so many of us, a few months ago I stumbled across the viral 2025 preprint of the “Your Brain on ChatGPT” study by Kosmyna et al. The paper sets off a real fireworks display of methods, and its result, broadly speaking, is that people who write texts with the help of ChatGPT are probably less cognitively challenged than those who formulate the texts themselves. But can it really surprise us that ready-made answers don’t make us smarter? And what does this have to do with good coaching?
Like so many of us, a few months ago I stumbled across the viral 2025 preprint of the “Your Brain on ChatGPT” study by Kosmyna et al. The paper sets off a real fireworks display of methods, and its result, broadly speaking, is that people who write texts with the help of ChatGPT are probably less cognitively challenged than those who formulate the texts themselves. At the same time, the final text does feel like their own work – yet they can’t really quote from it.
That got me thinking: can it really surprise us that using a chatbot as an answer machine doesn’t help knowledge stick? And what parallels are there to good coaching and effective teaching in general? Let me lay out what’s going through my head.
“Your Brain on ChatGPT” – What Was Studied?
Apart from the fact that, despite my basic training in psychology, I would struggle to reproduce every detail of the 206-page paper, doing so would certainly go beyond what you’re willing to read here. Still, I have to give a rough overview so we can discuss the experiment, and I have to go deeper than the general press did. Der Spiegel, for example, simplified it to “So doof macht uns ChatGPT” (“This is how dumb ChatGPT makes us”) – without even engaging with the study itself, but by interviewing someone who refers to it – while T-Online sensationally talks about “dramatic memory gaps” (translated from German). As so often, the researchers served it up far less hot than the clickbait factory would have us swallow it.
What the study actually examined is this: participants were split into three groups, each of which had 20 minutes to write essays across several sessions. The first group – Brain Only – had nothing but their own heads. The second group – Search Engine – was allowed to use Google for research (without the AI Overviews feature, of course), and the third group – LLM – was allowed to use ChatGPT while writing.
Over several rounds, different essays were produced, each monitored and accompanied by a range of methods. The result: the Brain Only group had to make the highest measurable cognitive effort and remembered their own essays best. The Search Engine group was in the middle, and the LLM group was the least cognitively challenged and was much worse than the other two groups at recalling quotes from their own essays. Interestingly, identification with one’s own work was strong in all three groups. So it’s not as if the LLM group felt they hadn’t done any work. In discussing the results, the authors focus above all on the risk of building up cognitive debt through LLM use, meaning that we increasingly use concepts we haven’t actually fully understood, which, accumulated over time, could become a problem for our ability to act autonomously.
The Study in Context: Truisms or Helpful Insights?
So what does this result really tell us about the effect of LLMs on our cognitive performance? Its transferability to everyday life is limited, to say the least! The first point is that 54 participants with similar demographics working on a limited task are not suited to supporting far-reaching conclusions; they merely provide an indication for further research, as the authors themselves of course note.
A second point, however, is far more important, and the researchers unfortunately didn’t flag it clearly: the experimental design captures only one specific way of using LLMs. The LLM group essentially consisted of “Copy & Paste Warriors” who, under time pressure, didn’t engage with the content but adopted ready-made answers.
So we are comparing three groups, two of which produced an essay and one of which had an essay produced. Two of which thought about the content and one of which had the thinking done for it. In this design, I can think of many other factors that have a much bigger effect on my cognitive engagement, and I’m sure the result would have turned out very differently if, for example, the goal hadn’t been to write an essay under time pressure but to gain a deep understanding of a topic.
The way the experiment was designed, though, we have learned less about what LLMs do to us cognitively than about the fact that you learn nothing from mere copying – a lesson you really should have learned while copying homework on the school bus.
Still, the study delivers valuable first insights: it shows empirically what we suspect intuitively, and it identifies an important psychological effect: strong identification with content produced by someone else. In the long run, this overconfidence could be more problematic than the copying itself, especially since we don’t have to be aware of our own inability.
Good Coaches vs. Bad Coaches
So, let’s sum up: simply imitating things without thinking doesn’t strengthen us cognitively. Not when producing an essay, and not when copying homework. Let’s bring this thought into focus with regard to coaching. The rule is: bad coaches give answers; good coaches ask questions that help you find the right answers yourself.
On the one hand, good coaches do this because they often don’t know the best answer themselves. Even when you are far ahead in expertise and experience, the coachee (the person being coached) is still the expert on their own situation, whose context changes the textbook answer. So answers are at most offers, which have to be assessed together for how well they fit the individual case.
Beyond the question of mindset, though, there is a much more important reason why good coaches rarely give answers: we learn early and quickly that clear answers may feel good in the short term, but they run diametrically counter to the actual goal of ethical coaching – making coachees independent of coaching as quickly as possible and strengthening their own resources.
The reason lies in the same mechanism that keeps LLMs from challenging us cognitively: you have to think things through yourself to truly absorb them into your own thinking. Otherwise, hardly any learning takes place. Only when you have thought through the pros and cons of different approaches yourself can you keep working with them and build on them. Coaches whose regular advice we become dependent on are just as bad as a slow drift into mindless output prompting.
How Can LLMs (Probably) Make Me Smarter in the Long Run?
So let’s take it as given that the cognitively underchallenged LLM group didn’t wither because of the nature of LLMs themselves, but because, under time pressure, they used LLMs to copy homework. What conclusion can we draw from this to counteract the effect?
The answer is to use LLMs like a good coach rather than a bad one. In concrete terms: use them to generate questions and lines of thought, not to produce ready-made answers that I become dependent on in the long run. Here are my three strategies:
The first strategy is to bring in LLMs only late when reflecting on complex problems, even though the structuring they offer is tempting. For developing your own thinking, it is incredibly valuable to first sit down in peace and slowly think through which problems you see, what a suitable target picture looks like, and what sensible first steps might be. Only once you’ve done the cognitively demanding work is an exchange with a chatbot worthwhile – at least if you aim to take ownership of the result of your work rather than just generate output quickly.
The second strategy is to use LLMs deliberately to generate questions instead of answers. For example, don’t prompt “How can I deal well with my stakeholder?” Instead, take your time to describe for yourself which problems you see with your stakeholders, what a target picture looks like, and what your first step would be, and use this as input for a prompt in which you specifically ask: “What could be a blind spot in my description?” The answer you get stimulates your thinking further without closing it off. A pleasant side effect is that one weakness of LLMs doesn’t come to the surface: their tendency to find out too little about context.
The third strategy would be not to lose sight of the exchange with people amid all the experimenting. For startup and product topics, for example, a good coach comes to mind. Book a free intro call with Jan Hoppe now. 🙃 But it doesn’t have to be a professional right away. Reach out, learn from people, and take along the side effect that exchanging with people is good for us: Loneliness, for example, is no longer at its 2020 level of 30%, but at 10–15% it is still well above pre-pandemic levels. So mutual support doesn’t just help you with open questions; it helps your well-being in the long run. Let’s not forget that amid all our enthusiasm for technology.
So What Have We Learned About Learning with LLMs?
Generative AI chatbots are tools we can use in different ways in our digital product work. We can use them to strengthen our work or to partly outsource it. Just as we aren’t surprised when a manager who only hands out tasks and otherwise leaves team members to their own devices doesn’t understand the details of their own department, we shouldn’t be surprised when a quickly prompted and then copied GPT output doesn’t add up to greater competence. Depending on the situation, we should therefore treat generative AI sometimes like a classmate whose homework gets copied – and sometimes like a teacher whom we approach with well-thought-out questions and who can lead us to new ideas.